 Stealth Model Watch
Evidence-normalized comparison · Updated Aug 27, 2026
Ox Alpha vs Qwen3.8-Flash
Ox Alpha’s identity is closed: Z.AI released it as GLM-5.3-Flash (320B-A18B). Qwen3.8-Flash is a production service based on the open-weight Flash-Next model. What is not closed is a fair benchmark winner or a complete production-price comparison.
First-screen verdict
Four claims, separated by evidence status
- Ox identity
- Z.AI GLM iteration Confirmed on the record
- Official model
- GLM-5.3-Flash 320B total · 18B active
- Qwen relationship
- Production Flash based on Next Confirmed by Qwen
- Fair benchmark winner
- Unresolved Protocols do not match
Identity hygiene
Name normalization: five labels, three product layers
The most common comparison error is treating a preview ID, a released model, a separate flagship SKU and a production service as interchangeable.
stealth/ox-alpha Historical preview ID The free OpenRouter model ID used from Aug 20 through the Aug 26 sunset.
GLM-5.3-Flash
GLM-5.3-Flash Official released model Z.AI’s official 320B-A18B name and open-weight repository.
Ox Alpha revealed
z-ai/glm-5.3 Separate flagship SKU A distinct OpenRouter model. Its $1.40/$4.40 pricing must not be assigned to Ox.
Not the Flash SKU
Qwen3.8-Flash Production service Based on Next, with default 1M context and official built-in tools.
Service layer
Qwen3.8-Flash-Next Open-weight technical basis The documented 125B/6B model and early preview of the Qwen4 architecture.
Weights layer
Price trap: the $1.40/M input and $4.40/M output
figures belong to the separate z-ai/glm-5.3 flagship SKU, not the Ox Alpha
preview or GLM-5.3-Flash.
OpenRouter flagship listing ↗
Dated snapshot
Availability and pricing: only one price is verified
These are product-state snapshots, not evergreen promises. Missing prices remain missing instead of being filled with a neighboring SKU.
Ox Alpha preview
$0 input · $0 output
Per million tokens on OpenRouter during the preview. The listing scheduled the preview to end on Aug 26, 2026. A stable post-preview API price is not established by this snapshot.
- Preview ID
- stealth/ox-alpha
- Status
- Sunset Aug 26
Qwen3.8-Flash production
Input NOT FOUND · Output NOT FOUND
The captured official pricing page did not expose an exact Qwen3.8-Flash row. This does not mean the service is free, unavailable or priced like another Qwen model.
- Production relation
- Based on Next
- Exact rollout
- NOT FOUND
Complete comparison
Nine dimensions, with one row per model
Every row carries its own scope and caveat. Qwen architecture fields describe Next unless production parity is explicitly confirmed.
| Dimension | Model / product layer | Verified value | Evidence boundary |
|---|---|---|---|
| Total / active parameters | GLM-5.3-Flash | 320B total · 18B active | HIGH · official post-release sources |
| Qwen3.8-Flash / Next basis | 125B total · 6B active; plus 51B n-gram embedding and 4B MTP | HIGH for Next; do not relabel the sum as an official 180B parameter count | |
| Architecture | GLM-5.3-Flash | Detailed expert count and layer layout not stated in this comparison record | Leave undisclosed fields blank; do not inherit them from another GLM SKU |
| Qwen3.8-Flash / Next basis | Multimodal MoE · 48 layers · 512 experts · 10 routed + 1 shared active per token | HIGH for Next | |
| Context window | Ox Alpha preview | 1,048,576 context · 131,072 max completion | HIGH · OpenRouter preview listing/API |
| Qwen3.8-Flash / Next basis | 262,144 native → 1,000,000 extensible; production Flash defaults to 1M | HIGH for published relationship; production max output not found | |
| Input / output modalities | Ox Alpha preview | Text + image + video → text | HIGH · preview endpoint |
| Qwen3.8-Flash / Next basis | Next supports text, image and video → text | HIGH for Next; full production endpoint parity unresolved | |
| API pricing per 1M tokens | Ox Alpha preview | $0 input · $0 output; post-preview stable price not found | HIGH for preview · unresolved after sunset |
| Qwen3.8-Flash production | Input not found · output not found | Do not substitute Max, 27B, 3.7-Flash or third-party prices | |
| Open weights / license | GLM-5.3-Flash | Weights landed Aug 26 in zai-org/GLM-5.3-Flash · MIT | Official repository now closes the earlier announced-only state |
| Qwen3.8-Flash-Next | Weights available · Qwen Community License 1.0 | Custom commercial conditions apply; not Apache or MIT | |
| DeepSWE evidence | Ox Alpha | Run A 58.4% (66/113) · Run B 64.6% (73/113) | Two community runs; Run B used a more generous per-task timeout |
| Qwen3.8-Flash-Next | 58.7 on DeepSWE 1.1 | Vendor-reported; highest of two harness configurations | |
| OpenRouter usage snapshot | Ox Alpha | 23.2T tokens/week · #1 through Aug 25 | Adoption, not model quality |
| Qwen3.8-Flash | No attributable exact-SKU record found in the captured snapshot | Not the same as zero usage | |
| Release / availability | Ox Alpha → GLM-5.3-Flash | Preview Aug 20; identity and open weights Aug 26; preview sunset Aug 26 | Historical preview is not a production SLA |
| Qwen3.8-Flash / Next | Next repository Aug 26; exact production rollout date not found | Weights availability and production API availability are separate claims |
9 dimensions · 18 model rows · snapshot updated Aug 27, 2026
Protocol before score
DeepSWE normalization: three numbers, no winner
The percentages sit close together, but the runs do not share a single protocol. Numeric proximity is not experimental equivalence.
Ox · Community Run A
58.4%
66 / 113 tasks
- pier 0.3.1 + mini-swe-agent
- Docker · 20h 39m
- 5 timeouts
Ox · Community Run B
64.6%
73 / 113 tasks
- DeepSWE v1.1
- mini-swe-agent 2.4.6
- Per-task timeout moderately relaxed
Qwen · Vendor report
58.7
DeepSWE 1.1
- Claude Code + mini-SWE-agent tested
- 256K · temp 1.0 · top_p 0.95
- Higher of two harness results reported
What can actually be deployed
Architecture and deployment
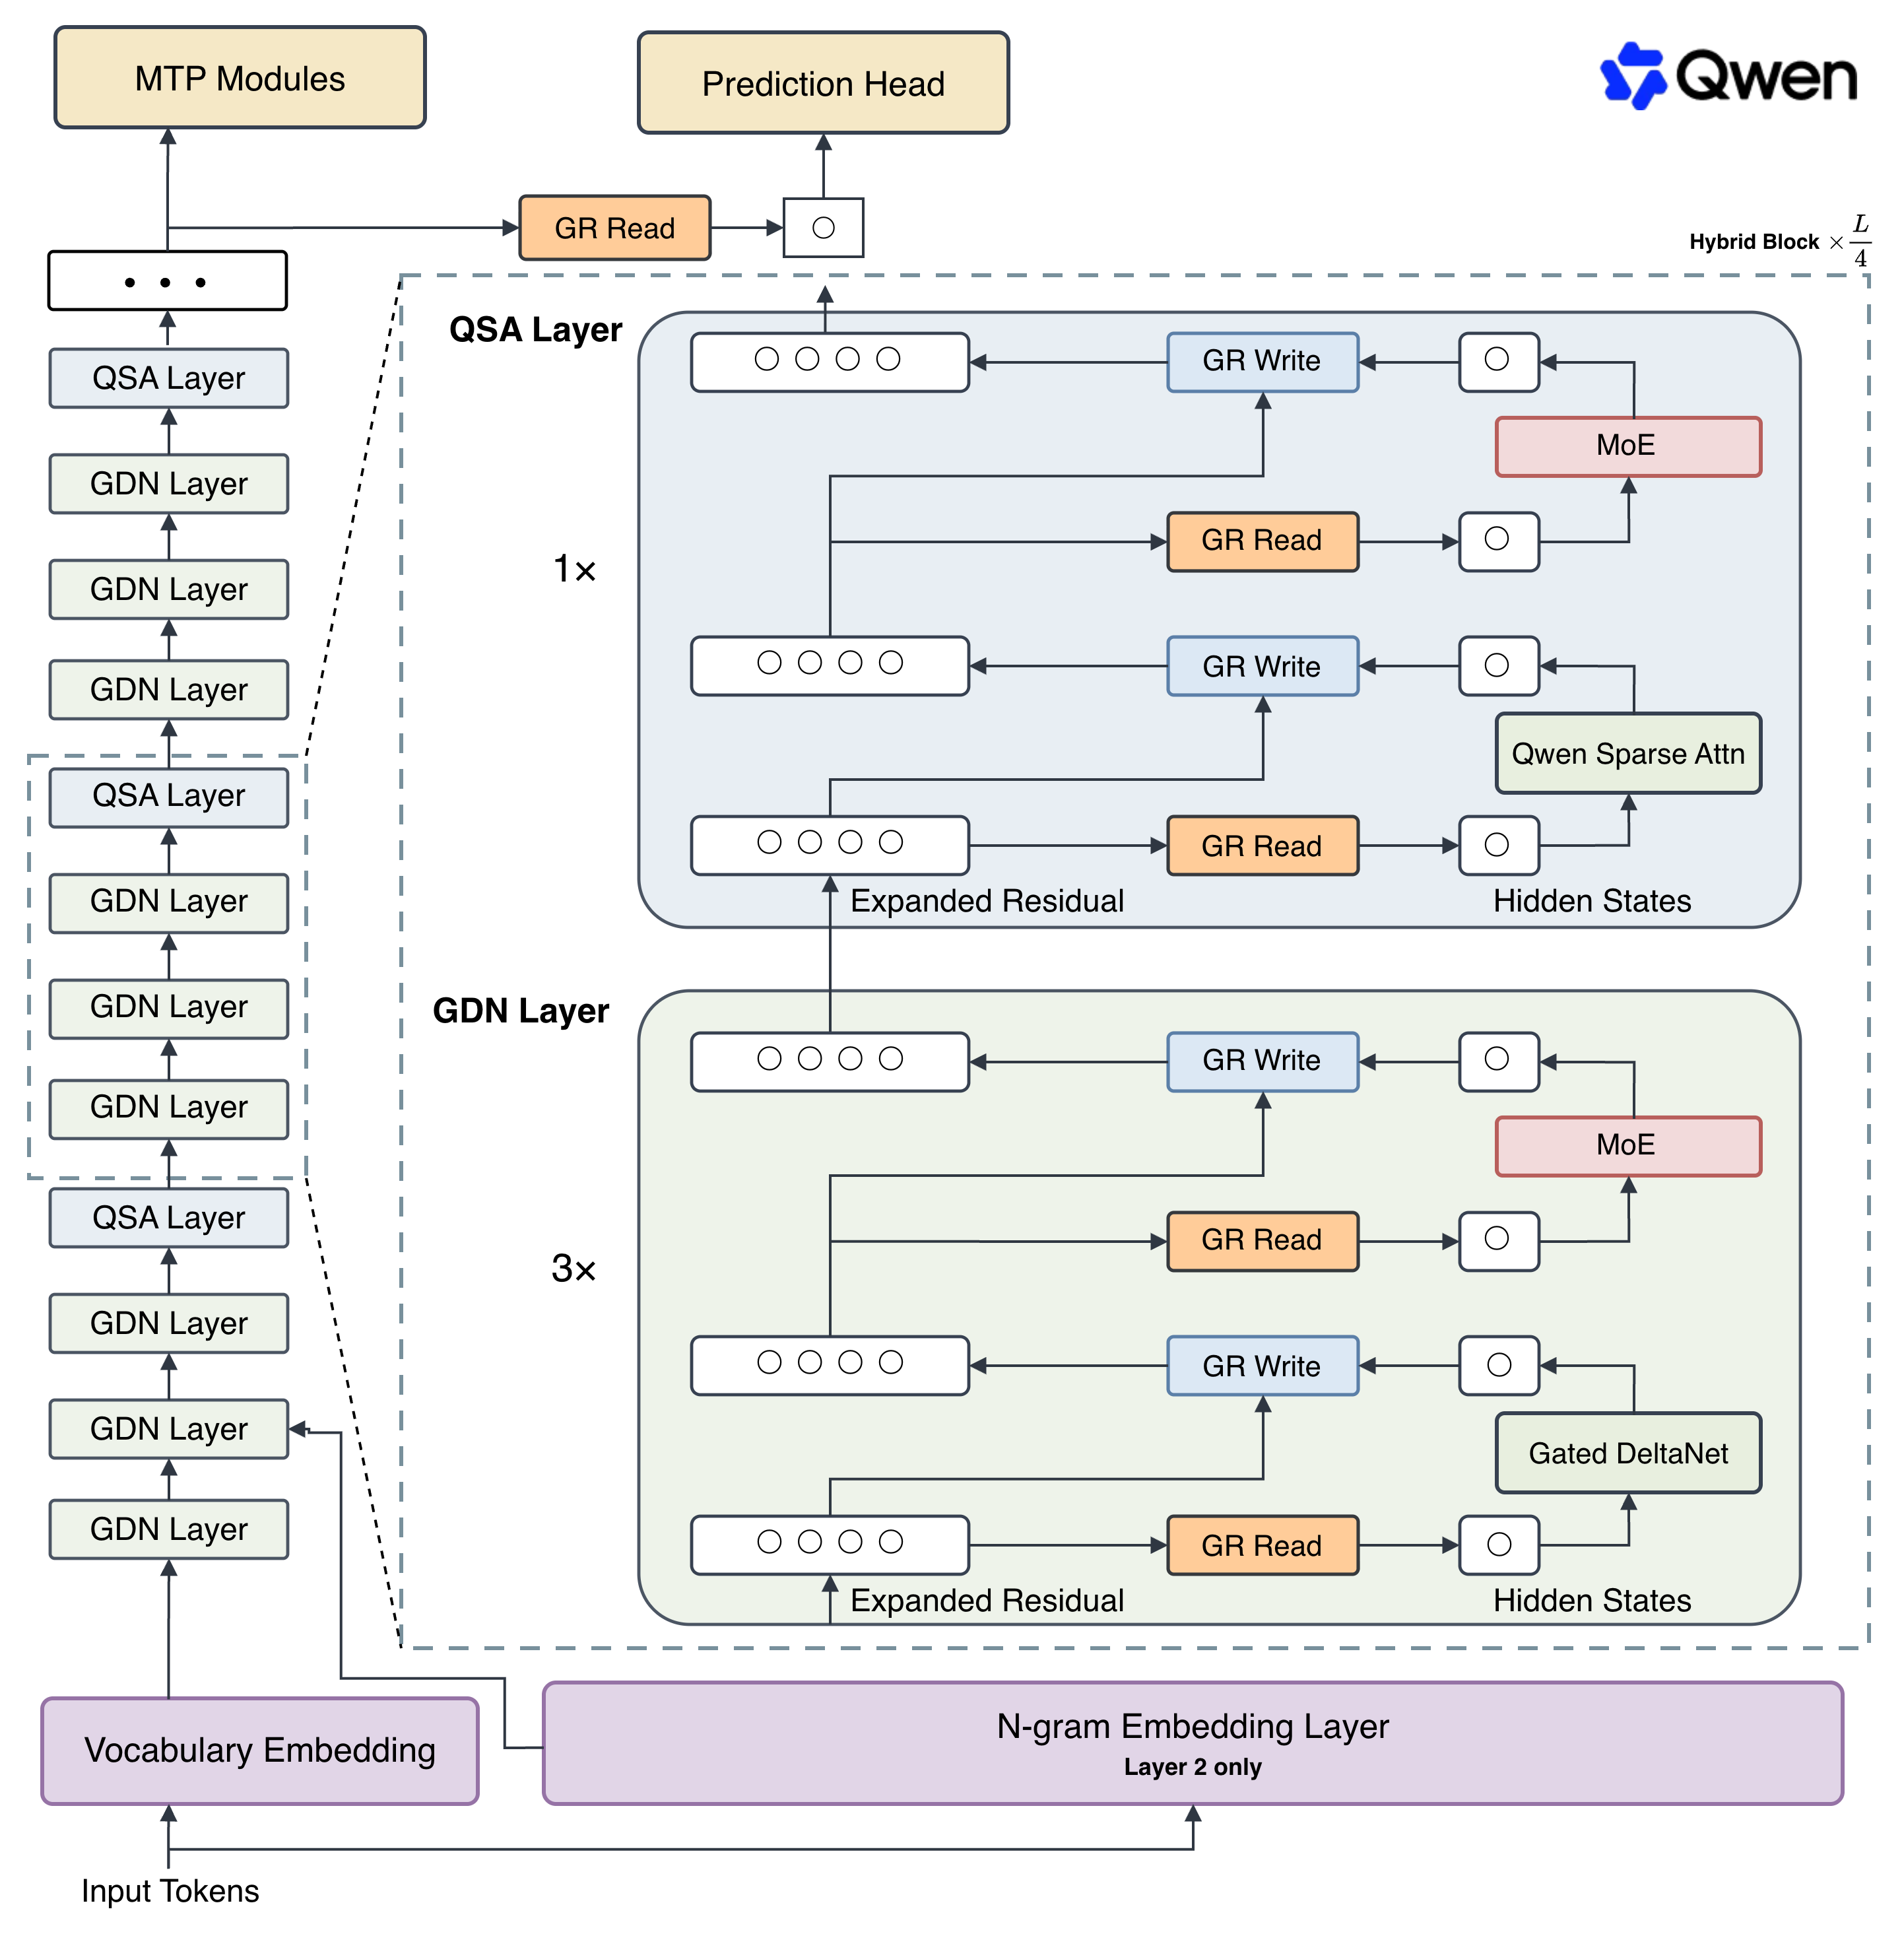
Qwen Next publishes a detailed blueprint. GLM-5.3-Flash now publishes its size, but this record does not invent missing expert-layout fields.
GLM-5.3-Flash
320B / 18B active
- Official weights
- FP8 + BF16 repositories
- Preview context
- 1,048,576 tokens
- Expert count
- Not stated here
- Layer layout
- Not stated here
- Published runtime VRAM
- Not found
Qwen3.8-Flash-Next
125B / 6B active
- MoE experts
- 512
- Per-token routing
- 10 routed + 1 shared
- Layers
- 48
- Context
- 262K native → 1M extensible
- Architecture role
- Early Qwen4 preview
Qwen also lists separate 51B n-gram embedding and 4B MTP components. Adding these numbers to 125B yields 180B arithmetically, but Qwen’s official # Params label remains 125B; this page preserves the vendor’s naming.
Weights are not licenses
Open-weight status and license boundaries
The old Ox snapshot ended at an announcement. The official repository now closes that gap; Qwen’s custom license still needs a commercial-use reading.
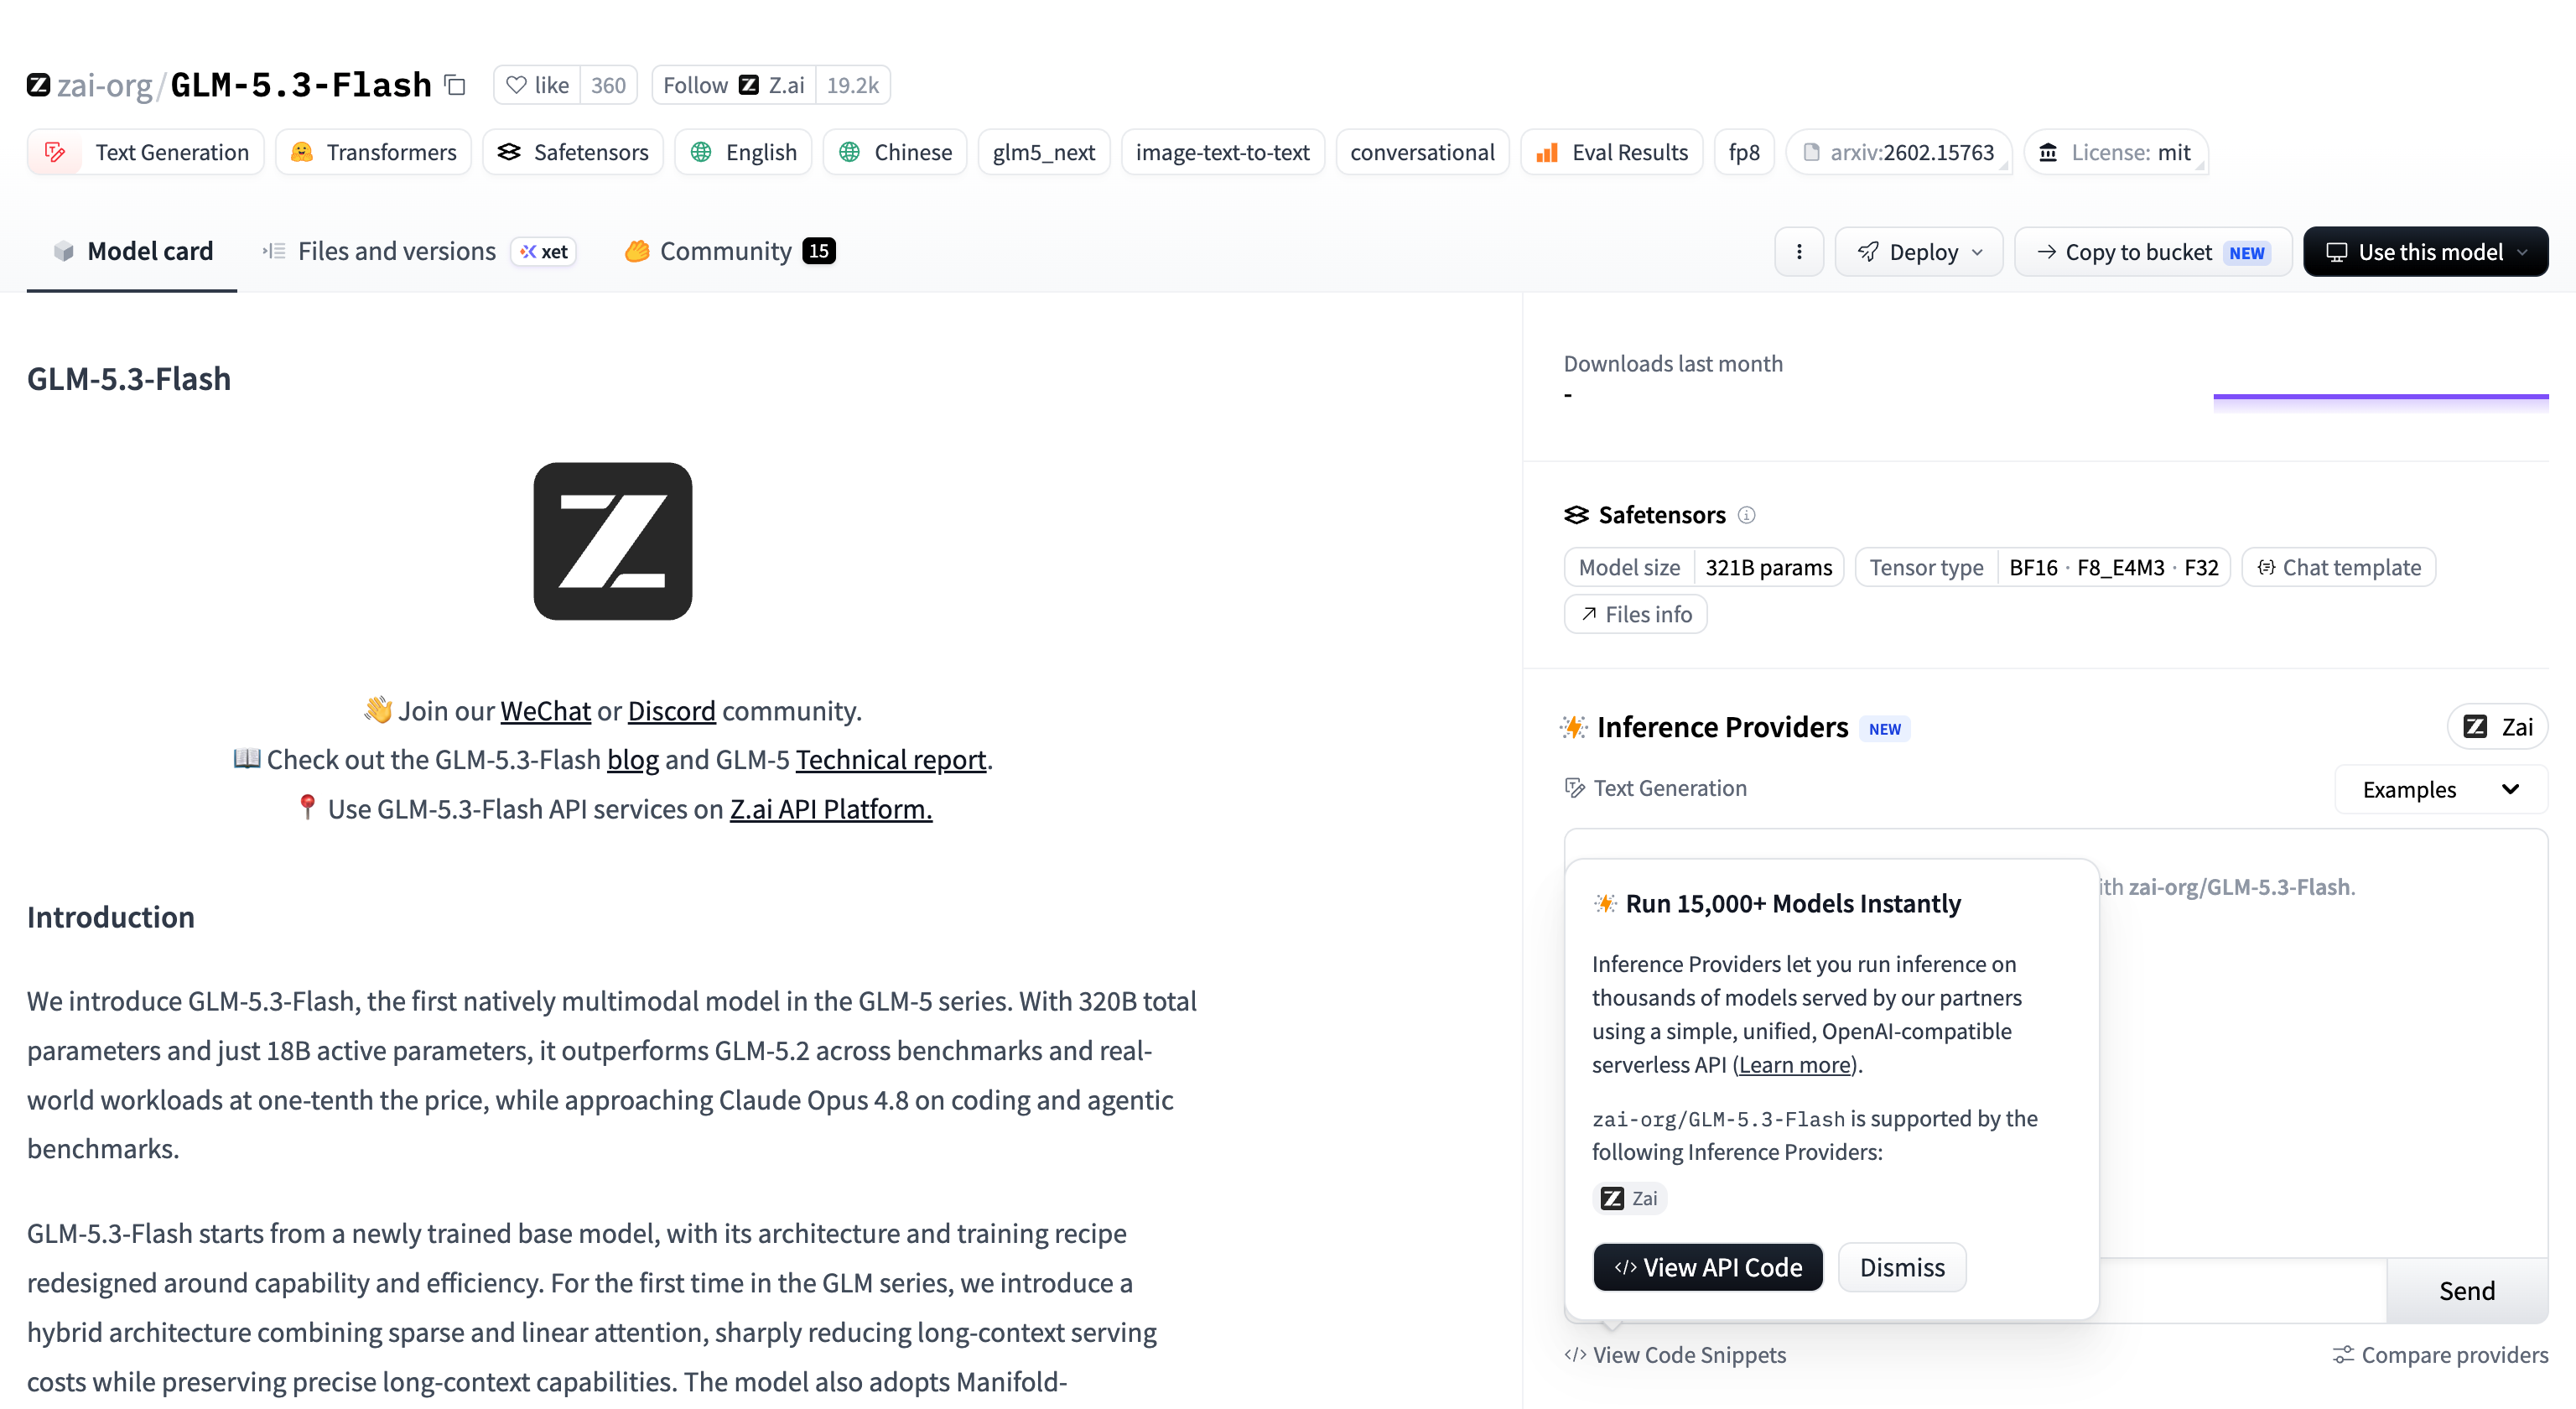
GLM-5.3-Flash
Landed
Z.AI announced the release on Aug 26, then published the model card and weights under
zai-org/GLM-5.3-Flash. License: MIT. The identity and delivery are no
longer pending.
Qwen3.8-Flash-Next
Custom licenseThe weights are downloadable under Qwen Community License 1.0. Large commercial products have model-name display obligations, and commercial MaaS or AI Work Assistant use generally requires a separate Qwen license, subject to the license’s internal-use exception.
Decision guide
Who should choose what
Choose from the constraint you can verify today, not from a headline benchmark.
Need detailed open-weight architecture documentation
Start with Qwen3.8-Flash-Next. Its 125B/6B structure, expert routing, context semantics, files and license are explicitly documented.
Need the released model behind the Ox preview
Use GLM-5.3-Flash’s official Z.AI repository. Do not build a production dependency around the retired stealth/ox-alpha preview ID.
Need a predictable hosted API bill
Do not decide from this snapshot alone. Ox’s verified $0 figure was preview-only, and an exact Qwen3.8-Flash production input/output price was not found.
Need the stronger coding agent
Run a controlled bake-off on your own repositories. The available DeepSWE scores are useful signals, but they do not establish a fair winner.
Change record
Dated update log
Identity, availability and price are time-sensitive. Each revision records exactly what changed.
-
Official GLM-5.3-Flash identity and repository applied
Replaced the pre-release unresolved alias state with Z.AI’s official GLM-5.3-Flash (320B-A18B) release, technical blog and Hugging Face repository.
-
Research snapshot frozen
Captured Ox preview availability and pricing, Qwen Next architecture, both Ox DeepSWE runs, Qwen’s vendor result and the production-price gaps.
-
Qwen3.8-Flash-Next weights published
Added the official model card, repository files and Qwen Community License 1.0 as the technical basis for the production Flash relationship.
Direct answers
Ox Alpha vs Qwen3.8-Flash FAQ
Short answers that preserve the same evidence boundaries as the comparison above.
What is the official model name behind Ox Alpha?
Z.AI officially released the former stealth preview as GLM-5.3-Flash, a 320B-total, 18B-active model. The OpenRouter preview ID was stealth/ox-alpha.
Is Qwen3.8-Flash-Next the same as Qwen3.8-Flash?
No. Qwen says the production Qwen3.8-Flash service is based on Qwen3.8-Flash-Next. Next is the open-weight technical basis; the production service adds default 1M context and built-in tools, and full endpoint parity is not documented.
Is Ox Alpha still free?
The stealth/ox-alpha OpenRouter preview was priced at $0 per million input and output tokens and was scheduled to end on August 26, 2026. A stable post-preview API price was not found in the comparison snapshot.
Which model wins the DeepSWE benchmark?
No fair winner can be selected from the published results. Ox Alpha community runs scored 58.4 and 64.6, while Qwen reported 58.7, but the harnesses, timeouts, context settings and reporting rules were not identical.
Are both models open source?
Both have downloadable weights. GLM-5.3-Flash is available from Z.AI on Hugging Face under MIT. Qwen3.8-Flash-Next uses the custom Qwen Community License 1.0, which includes commercial conditions, so open-weight is the more precise label.